A peptide is a short chain of amino acids, a polypeptide is a longer continuous chain, and a protein is one or more folded polypeptide chains that carry out a biological function. The distinction is a matter of length and folding, not a different chemistry: every peptide bond in a two-residue dipeptide is the same bond holding together a 300-residue collagen strand.
The conventions researchers actually use:
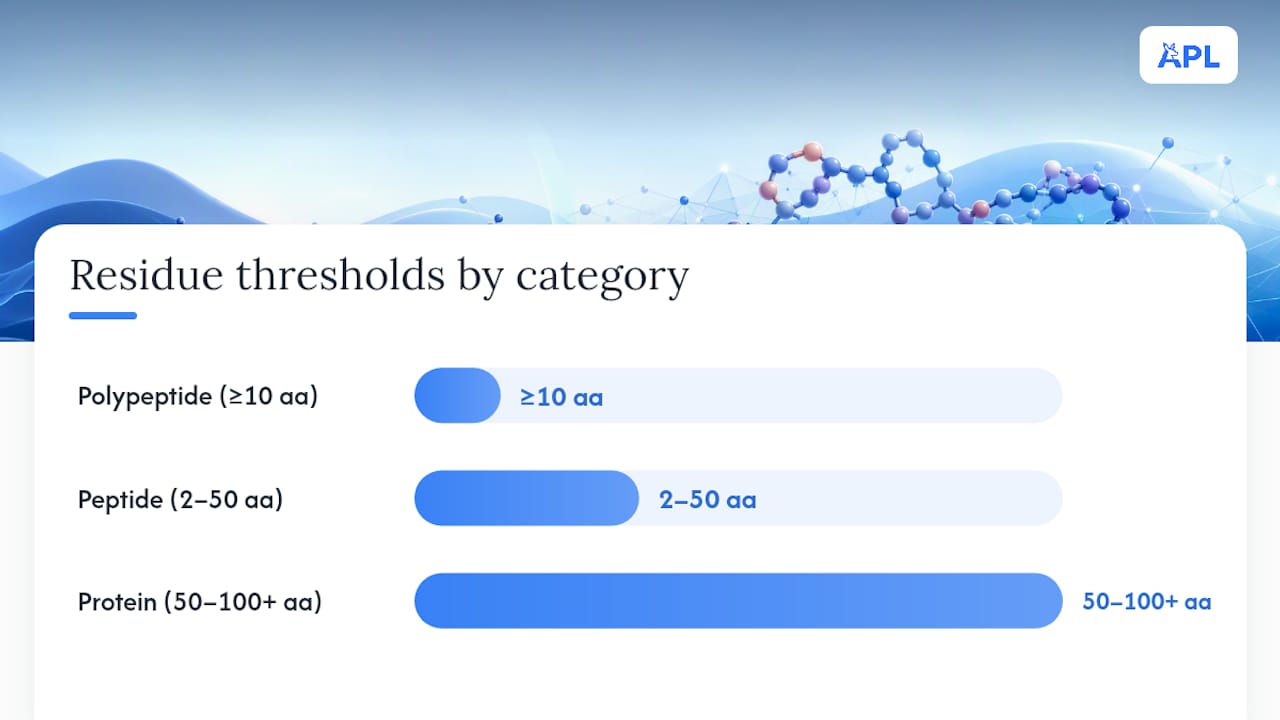
- Polypeptide: IUPAC defines this as a peptide containing ten or more residues, a category that overlaps deliberately with the upper end of "peptide."
- Protein: typically 50–100+ residues, or a molecular mass above roughly 10 kilodaltons, once the chain has folded into a stable three-dimensional structure.
None of these thresholds are legal boundaries. They are working conventions that shift slightly depending on which textbook, glossary, or laboratory you ask.
Size matters most once you consider what a molecule can actually do once it leaves a vial. A widely cited threshold for passive diffusion through intact skin sits at around 500 Daltons — a rule of thumb pharmaceutical formulators use to predict whether a topical active has any chance of crossing the stratum corneum unassisted. Most peptides used in skincare, and virtually every polypeptide or protein, sit well above that mass.
Peptide vs polypeptide: what actually separates the two terms
The word "peptide" describes any molecule built from amino acids joined by peptide bonds, generally capped at somewhere between two and fifty residues. A polypeptide is the same chemistry stretched longer. There's no different bond, no different backbone chemistry, just more of it. IUPAC's own glossary entry states plainly that polypeptides are peptides containing ten or more amino acid residues, which means the two categories overlap for a stretch between ten and fifty residues where a molecule could reasonably be called either.
Picture the peptide bond itself: it's the covalent link between the carboxyl carbon of one amino acid and the amino nitrogen of the next, releasing a water molecule in the process (a condensation reaction). String together enough of these bonds together and you get a repeating backbone, amino acid, bond, amino acid, bond, with side chains hanging off each residue like charms on a bracelet. That backbone is identical whether you're looking at a two-residue dipeptide or a 1,000-residue polypeptide. Length is the only variable.
Some working examples make the categories concrete:
- Dipeptides and tripeptides — the shortest functional peptides, often used as building blocks or signalling fragments in research.
- Insulin — a peptide hormone of 51 residues arranged across two short chains, illustrating how even a well-known "peptide" sits right at the boundary with polypeptide territory.
- Antimicrobial peptides, such as those studied in laboratory settings for their membrane-disrupting activity, typically run 12 to 50 residues.
- Skincare di- and tripeptides, like the copper-binding and signal peptides marketed in serums, sit at the very short end of the scale, which is precisely why formulators favour them for topical use.
Naming conventions aren't fixed across every field. A biochemist might call a 40-residue chain an "oligopeptide," while a pharmaceutical scientist studying the same molecule as a drug candidate might simply call it a "peptide therapeutic." Readers wanting the formal chemical definitions can check Au Peptide Labs' glossary entry on net peptide content for how purity and residue count get documented in practice.
As University of Queensland researcher Mark Blaskovich notes, the boundary between these categories is intentionally loose. The functional reality is a size and complexity continuum, and precise residue counts matter more than which label gets attached to a molecule.
What a polypeptide is and how it becomes a protein
A polypeptide is a single, continuous chain of amino acids long enough to begin folding into a stable shape rather than flopping around as a loose string. IUPAC's phrasing, again, sets the formal threshold at ten or more residues, but the practical shift that matters happens further up the scale, once a chain is long enough to fold reliably into secondary structures like alpha helices and beta sheets.
Collagen is the clearest illustration available. Individual collagen polypeptide chains, each one a long, repetitive sequence rich in glycine and proline, wind around each other in triples to form a tough triple helix. That triple helix is the structural protein researchers actually study; the individual polypeptide chain on its own is just raw material. Fold three of them together correctly, and you get one of the most abundant structural proteins in the human body. Fold them incorrectly, or leave them unassembled, and you get nothing functionally useful at all.
Folding is what converts a chain into a working molecule, and it does several specific things:
- Creates active sites — enzymes fold into precise 3D pockets that bind substrates; an unfolded chain has no such pocket.
- Enables stable multimer assembly — many proteins, collagen included, only function once multiple chains combine.
- Extends functional stability — a folded structure resists degradation far better than an exposed linear chain.
- Determines enzymatic activity — catalytic function depends on the exact geometry folding produces, not just the sequence.
Length alone doesn't guarantee any of this. A polypeptide chain twice the size of another isn't automatically twice as functional; post-translational modifications (like glycosylation or phosphorylation), correct folding chaperones, and final assembly into multi-chain complexes all determine whether a chain becomes a working protein or just an inert string of residues.
Chain length correlates with rising manufacturing complexity, cold-chain storage demands, and immunogenicity risk, a pattern documented in research examining how the term "peptide" is used contextually across pharmaceutical and academic settings.
How scientists actually define these size boundaries
The numeric conventions floating around the literature come from a handful of authoritative sources, and it helps to see them side by side rather than piecemeal.
| Category | Common threshold | Primary source | | --- | --- | --- | | Peptide | Roughly 2–50 amino acid residues | NCBI Bookshelf, Biochemistry: Peptide | | Polypeptide | 10 or more residues (formal definition) | IUPAC Goldbook | | Protein | Typically 50–100+ residues, or >10 kDa | NCBI Bookshelf, Biochemistry: Peptide |
Public science glossaries echo the same rough numbers. The Genome defines a peptide as a short chain, typically 2 to 50 amino acids, and treats longer chains as polypeptides or proteins depending on length and folding state. Britannica's comparison uses the same basic split: peptides as the smaller chains, proteins as the larger, folded macromolecules built from one or more polypeptide chains.
None of these numbers are enforced by regulation. They're conventions that different textbooks and glossaries converge on because they're useful, not because any body has legislated them. That said, the exact count still matters enormously in practice. A synthesised chain that comes in at 48 residues instead of a claimed 45 can behave differently in an assay, and manufacturers who quote residue counts loosely make it harder for a lab to reproduce results. Storage conditions differ too: many longer polypeptides and proteins need cold-chain handling that a stable, short synthetic peptide doesn't require, and larger molecules generally carry a higher risk of triggering an immune response when used in biological research, a factor that shapes both formulation choices and study design, as context-dependent peptide research makes clear.
Why length and folding change what a molecule can do
Chain length is the raw material; folding is what turns that raw material into a working tool. A handful of mechanisms explain most of the practical differences between a short peptide and a folded protein:
- Active-site formation — folding brings distant residues into proximity, creating the geometry an enzyme needs to bind a substrate.
- Multimerisation — some functional units, haemoglobin among the best known, only work once multiple folded chains assemble together.
- Protease susceptibility — shorter, unfolded peptides are generally easier targets for digestive and tissue enzymes than tightly folded, compact proteins.
- Solubility and aggregation risk — longer chains are more prone to misfolding and clumping, a problem that drives much of pharmaceutical formulation science.
Molecular weight and three-dimensional shape together decide whether a molecule stands any chance of reaching viable tissue when applied topically. The 500 Dalton threshold for passive skin diffusion applies regardless of whether the molecule in question is technically a peptide or a polypeptide; what matters is mass and shape, not the label. A five-residue peptide might squeak under that line. A 30-residue polypeptide almost certainly won't, and a folded protein has no realistic chance at all.
Oral peptides are routinely broken down by digestive enzymes before they can act, which is well documented in pharmaceutical delivery research, and that same enzymatic vulnerability is a large part of why parenteral administration or specialised carrier systems (lipid nanoparticles, for instance) show up so often in peptide drug development. Longer polypeptides and folded proteins face the same problem, only worse, because their size rules out passive skin penetration entirely and their structural complexity makes them fragile outside carefully controlled conditions.
Formulation science exists largely to work around these limits. Stabilising excipients, encapsulation, and cold-chain logistics all trace back to the same underlying issue: the bigger and more folded a molecule is, the more engineering it takes to get it somewhere useful intact.
Real molecules that show the categories in action
Abstract definitions land better with concrete anchors. A few examples worth keeping in mind:
- Insulin — a 51-residue peptide hormone arranged in two chains linked by disulfide bonds; often called a 'peptide' despite sitting near the polypeptide threshold, illustrating how field-specific usage varies.
- Antimicrobial peptides — generally 12 to 50 residues, studied in laboratory settings for their capacity to disrupt bacterial membranes; their short length is central to how quickly they can be synthesised and tested.
- Collagen — individual polypeptide chains several hundred residues long, each one useless alone but functionally vital once three chains twist into the triple-helix structural protein that gives skin and connective tissue their strength.
- Enzymes such as lysozyme — a folded protein of roughly 129 residues, chosen here because its compact, well-studied active site demonstrates what folding adds that a linear chain of the same length couldn't provide.
Each of these sits at a different point on the same continuum, none of them defined by a different chemistry, just by different lengths and different folding outcomes.
Checking the label matters more than memorising the categories
The single most useful habit when reading either a scientific paper or a product spec sheet is to look past the word "peptide," "polypeptide," or "protein" entirely and check the exact residue count instead. A molecule described loosely as a "peptide" that turns out to be 48 residues long behaves far closer to a small protein than to a dipeptide, and that difference shows up in solubility, stability, and bioactivity, not just in terminology.
When evaluating a paper or a product's certificate of analysis, three details matter more than the category label: the exact amino-acid sequence and count, the stated purity (commonly above 99% for serious research applications), and the assay method used to confirm both. Small sequence deviations can meaningfully change how a molecule behaves, a point Wikipedia's peptide entry makes clearly, and it's a far more reliable signal than trusting a marketing description.
The categories themselves aren't rigid boxes; they're useful shorthand along a continuum where sequence and folding, not the label attached to a molecule, ultimately decide what it can do.
Where to verify these definitions yourself
The claims made throughout this article rest on a small set of sources worth bookmarking if you work with peptides regularly.
- IUPAC Goldbook, polypeptides entry — the formal chemistry definition setting the ten-residue polypeptide threshold.
- Genome — a plain-language public glossary entry, useful for a fast sanity check.
- Britannica, peptide vs protein explainer — accessible framing of folded proteins versus smaller peptide chains.
- University of Queensland IMB, peptides vs proteins explainer — the continuum framing referenced throughout this article, from a working research institute.
- PMC, peptide delivery and degradation issues — the technical basis for peptide degradation.
- Dermamedics, size and active ingredient penetration — the practical source for the 500 Dalton skin diffusion threshold.
- Au Peptide Labs glossary, net peptide content — a practical next step for readers who want formal terminology tied to procurement and purity documentation.
Frequently asked questions
Are peptides and polypeptides the same thing? No. Both are chains of amino acids joined by peptide bonds, but a peptide is conventionally short (roughly 2–50 residues) while a polypeptide is defined by IUPAC as containing ten or more residues. The two terms overlap in the middle of that range.
Is a peptide the same as a protein? No. A protein is one or more folded polypeptide chains performing a stable biological function. A peptide is much shorter and generally hasn't folded into the complex secondary and tertiary structures that define a protein.
Sources
- polypeptides (P04749) — IUPAC goldbook
- Explainer: peptides vs proteins — IMB, University of Queensland
- Peptide delivery and degradation issues — PMC article